Key Takeaways
- Execution Services teams can use KDB-X GPU Acceleration for compute-heavy q workloads that exceed fixed research, intraday, or overnight processing windows.
- KDB-X moves suitable joins, sorts, grouped calculations, and other parallel operations to NVIDIA GPUs while application state and unsupported logic remain on the CPU.
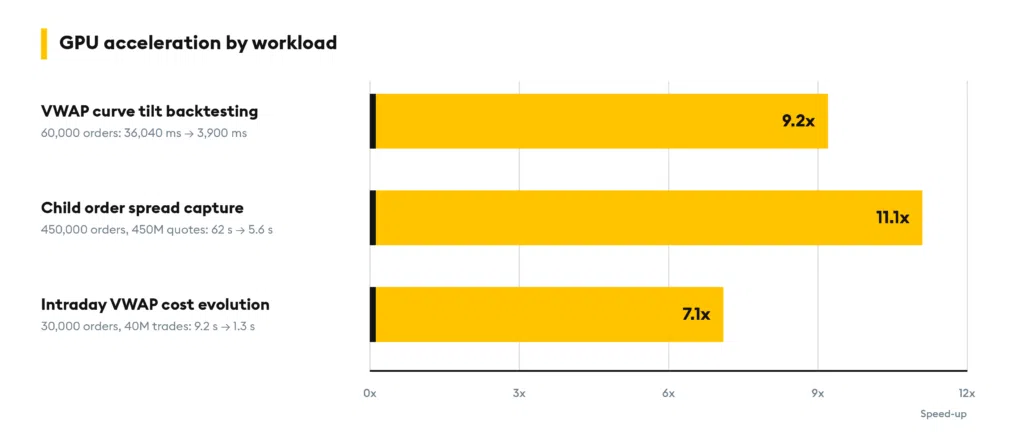
- Tier 1 bank tests recorded 7.1x to 11.1x speedups across VWAP backtesting, child-order spread capture, and intraday VWAP cost evolution.
- Shorter runtimes can support broader backtests, fuller order populations, and execution insight while the results can still inform the workflow.
- Teams should begin with one named q workload and benchmark it using representative data, a CPU baseline, clear timing boundaries, and defined success criteria.
An execution analytics result has a shelf life. A curve calibration that completes after the research cycle, a child-order analysis that finishes after trade date, or a cost signal that arrives after the session can still explain what happened. It cannot help the team act inside the original window.
As order, quote, history, and parameter volumes grow, execution teams may protect a deadline by narrowing a test, sampling data, or deferring the work. The constraint appears as fewer model iterations, less evidence for an order review, and less time to investigate an active issue.
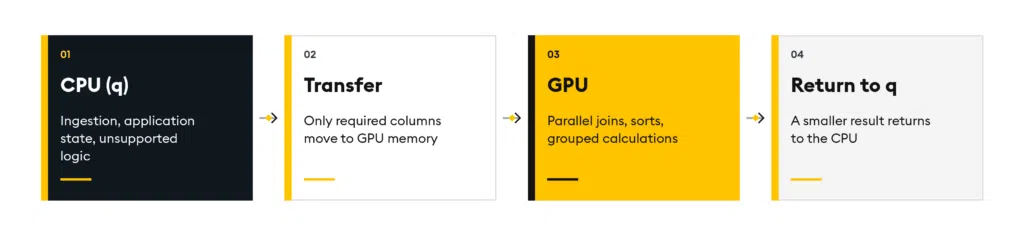
KDB-X GPU Acceleration addresses suitable performance-critical q paths while ingestion, application state, unsupported logic, and low-volume work remain on the CPU. Teams keep the application and schema in place, adapt the candidate path to supported GPU operations, and avoid building a separate CUDA implementation.
KDB-X GPU Acceleration Results for Three Execution Analytics Workloads
A faster function matters when it changes the operating window around it. That may mean completing a broader calibration sweep within the research cycle, checking a demonstrated child-order population on trade date, or returning intraday cost evolution while the session is active. The benchmark should begin with that workflow target.
| Execution workload | Published data volume | CPU | GPU | Change |
|---|---|---|---|---|
| Child order spread capture | 450,000 orders and 450 million quotes | 62s | 5.6s | 11.1x |
| Intraday VWAP cost evolution | 30,000 orders and 40 million trades | 9.2s | 1.3s | 7.1x |
| VWAP curve tilt backtesting | 60,000 orders | 36,040ms | 3,900ms | 9.2x |
Which Execution Analytics Workloads Were Tested With GPU Acceleration?
The published tests connect runtime to model cadence, analytical coverage, and decision timing. Each result is specific to the measured path. A customer workload still requires its own benchmark.
VWAP Curve-Tilt Backtesting With GPU Acceleration
VWAP algorithms depend on intraday volume profiles. When trading patterns change, teams need to test whether the current curve still describes the way volume is forming. A broad curve-tilt sweep can involve repeated joins and grouped or sliding-window calculations across order history. If it overruns the research cycle, the team reduces the sweep or waits longer to update the model.
In the published bank workload, 60,000 orders were processed in 3,900 milliseconds on the GPU, compared with 36,040 milliseconds on the 48-core CPU baseline. The measured change was 9.2x. In that demonstrated workload, the shorter runtime supported a weekly or daily recalibration cadence.
Child-Order Spread Capture Analysis With GPU Acceleration
A child-order review often aligns orders with a large quote history, then calculates metrics across the joined population. The row count can make that analysis expensive enough that the team samples data or waits for a later batch. That reduces the evidence available for investigating venue outcomes, passive fills, and spread capture.
The published test aligned 450,000 orders with 450 million quotes. Runtime fell from 62 seconds on the CPU baseline to 5.6 seconds on the GPU, an 11.1x change for the measured compute stage. The tested population could be checked on trade date. This does not establish that every child-order workflow can analyze every quote in real time; it shows what was possible for this data shape and boundary.
Intraday VWAP Cost Evolution With GPU Acceleration
Cost evolution analysis repeatedly aligns orders and trades as the session develops. Its value depends on when the result returns. A next-day answer can support review and reporting, but it cannot give the desk more time to investigate an active order or a changing execution trajectory.
In the published workload, 30,000 orders and 40 million trades were processed in 1.3 seconds on the GPU, compared with 9.2 seconds on the CPU baseline. The 7.1x measured change brought the result inside the session for the demonstrated path. Its value to another team depends on refresh cadence, concurrency, surrounding I/O, and the downstream workflow.
How Does KDB-X Divide q Processing Between CPUs and GPUs?
CPU and GPU memory are separate. A strong candidate performs substantial parallel work, moves only the required columns, reuses resident data where possible, and returns a smaller result to q. Moving a wide table for one short operation can erase the compute advantage.
The KDB-X .gpu namespace exposes supported data movement, queries, joins, sorting, append, and device functions. This keeps the accelerated path inside q, but it is not automatic offload. Candidate functions may require targeted adaptation, while unsupported or transfer-heavy paths should remain on the CPU.
Which Other Execution Analytics Workloads Are Candidates for GPU Acceleration?
Public evidence varies by use case, so treat these paths as candidates until the customer’s implementation is measured.
- Streaming TCA and markouts with resident intraday data and compact results
- Full-history backtesting and repeated parameter sweeps
- End-of-day sorting before corrections, reruns, or downstream reporting
- Algo and venue analysis across orders, fills, quotes, and benchmarks
How to Identify a q Workload for GPU Acceleration
Start with the q functions that dominate runtime, representative data volume, the CPU baseline, the processing deadline, and the decision the result supports. Then identify candidate GPU paths, likely exclusions, data-movement requirements, and a fair measurement boundary.
Use the same input, output, and success criteria on CPU and GPU. Record whether timing covers the compute stage or the full workflow, including I/O and result materialization.
Benchmark Your q Workload With KX
Bring one named q workload, its current runtime, representative data volume, and the window the team wants to improve. A KX engineer will review the candidate functions, data movement, hardware context, likely exclusions, benchmark order, and success criteria.
Is your CPU cluster starting to write IOUs against time-sensitive workloads? Learn more about KDB-X GPU Acceleration, or benchmark one of your existing workloads to see where it could help your firm buy back time.